Next
Papers near this one.
Walkthroughs
 5:28
Active Exploring like a Pigeon: Reinforcing Spatial Reasoning via Agentic Vision-Language Models
shares Video understanding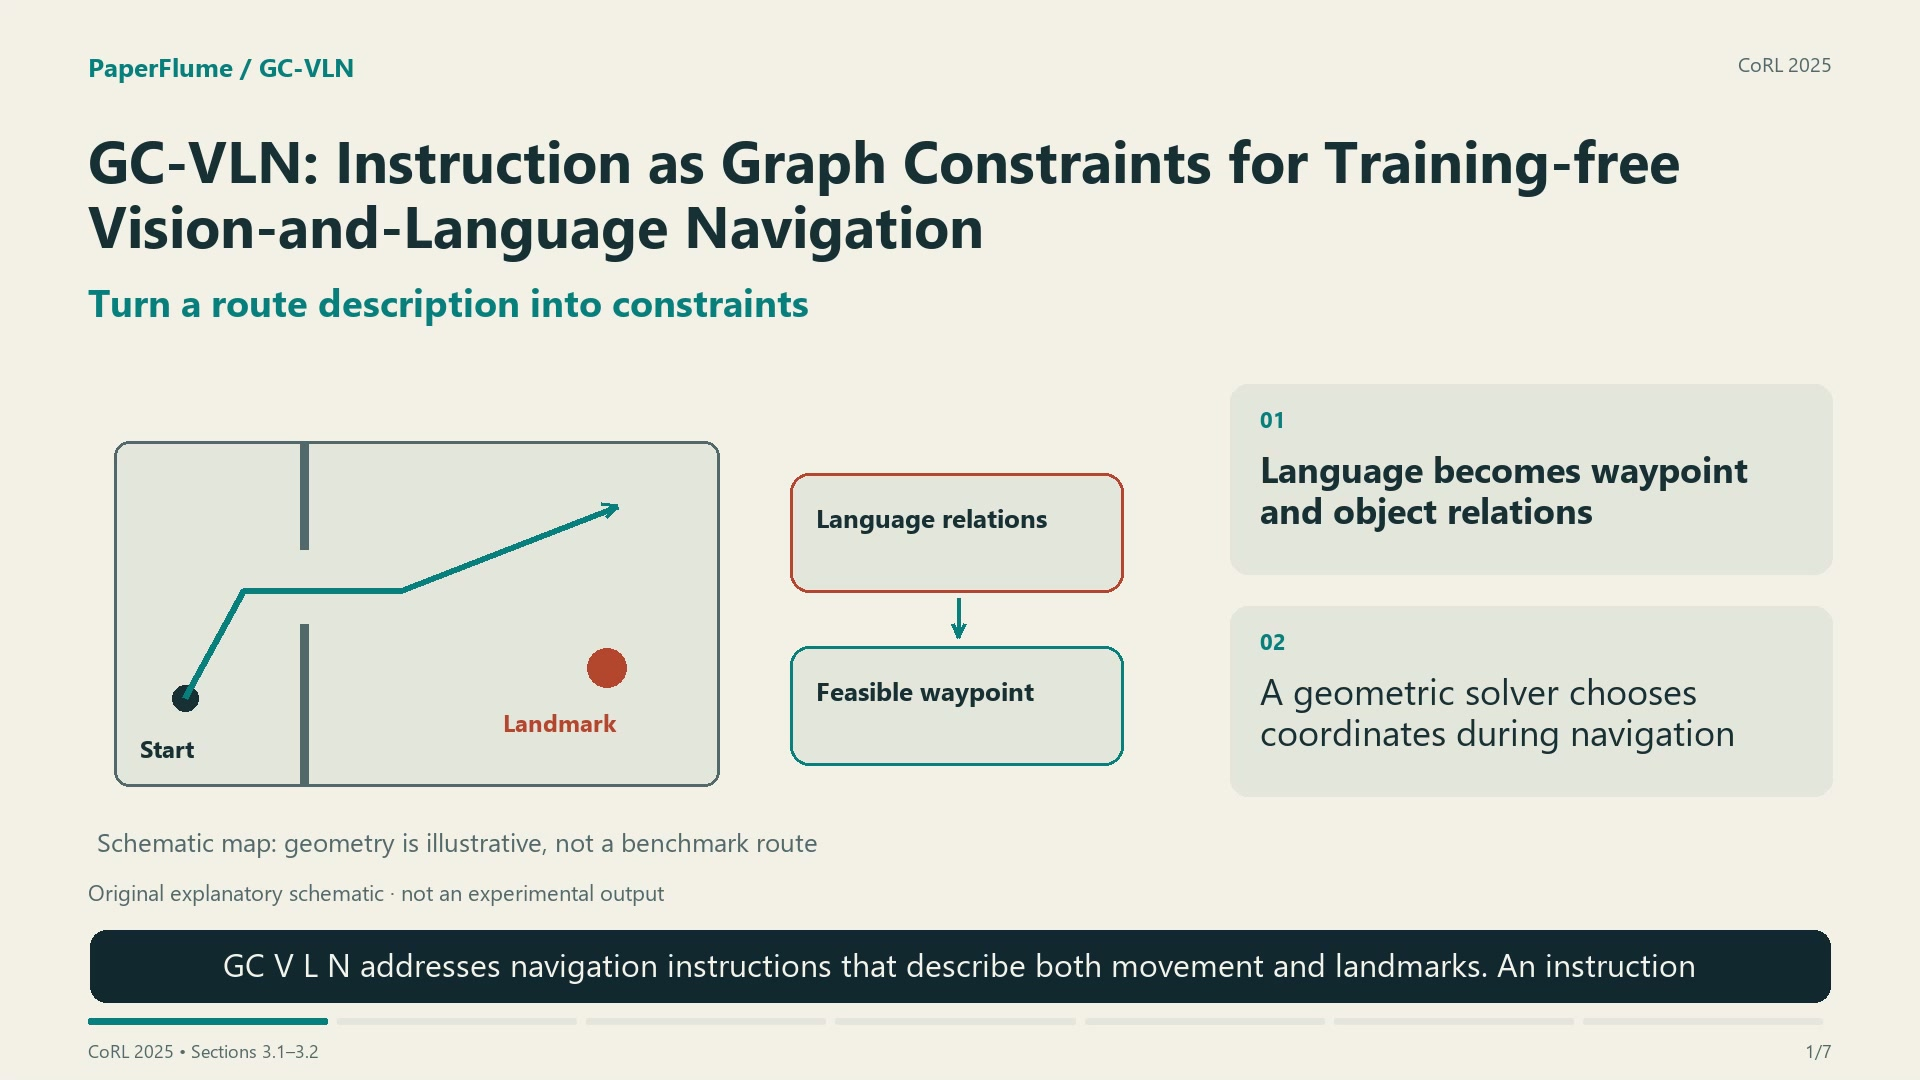 5:25
GC-VLN: Instruction as Graph Constraints for Training-free Vision-and-Language Navigation
shares Vision-language navigation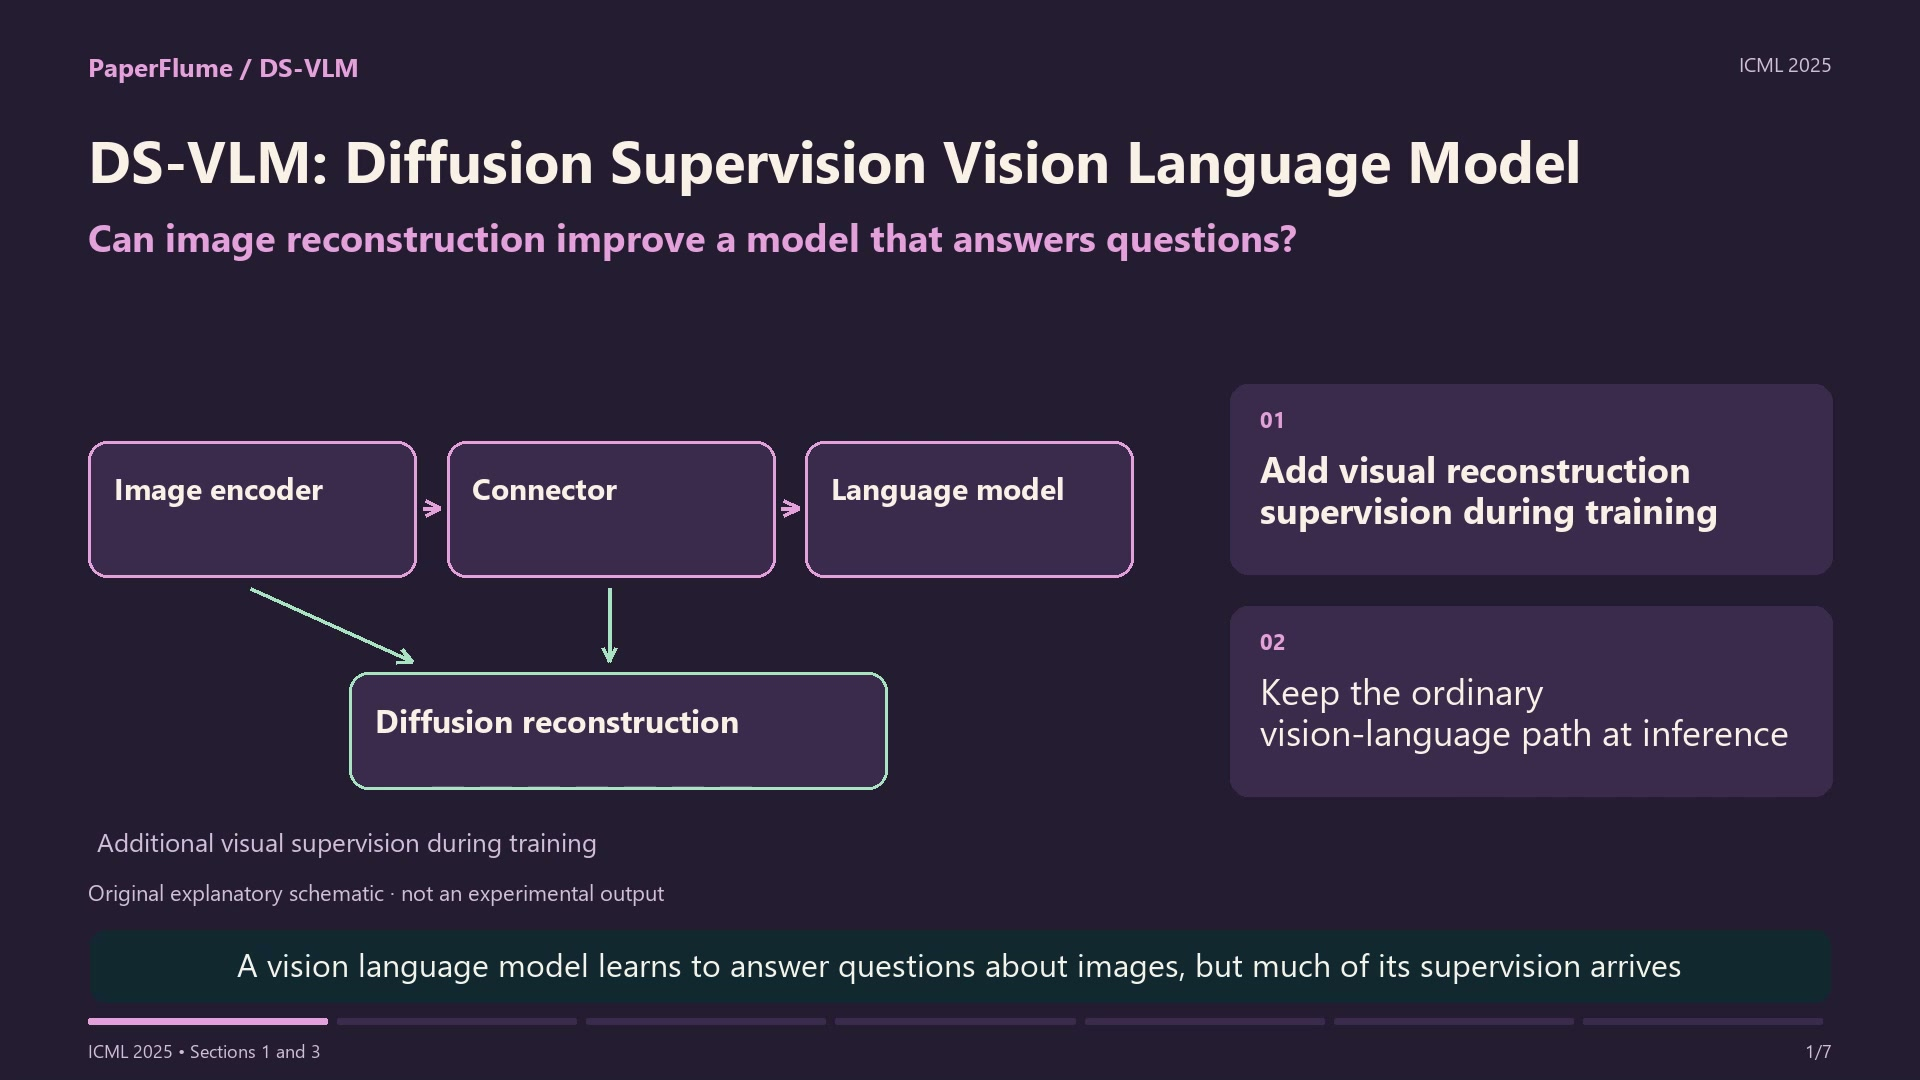 5:42
DS-VLM: Diffusion Supervision Vision Language Model
shares Diffusion modelsShort cuts
 0:59
Active Exploring like a Pigeon: Reinforcing Spatial Reasoning via Agentic Vision-Language Models
shares Video understanding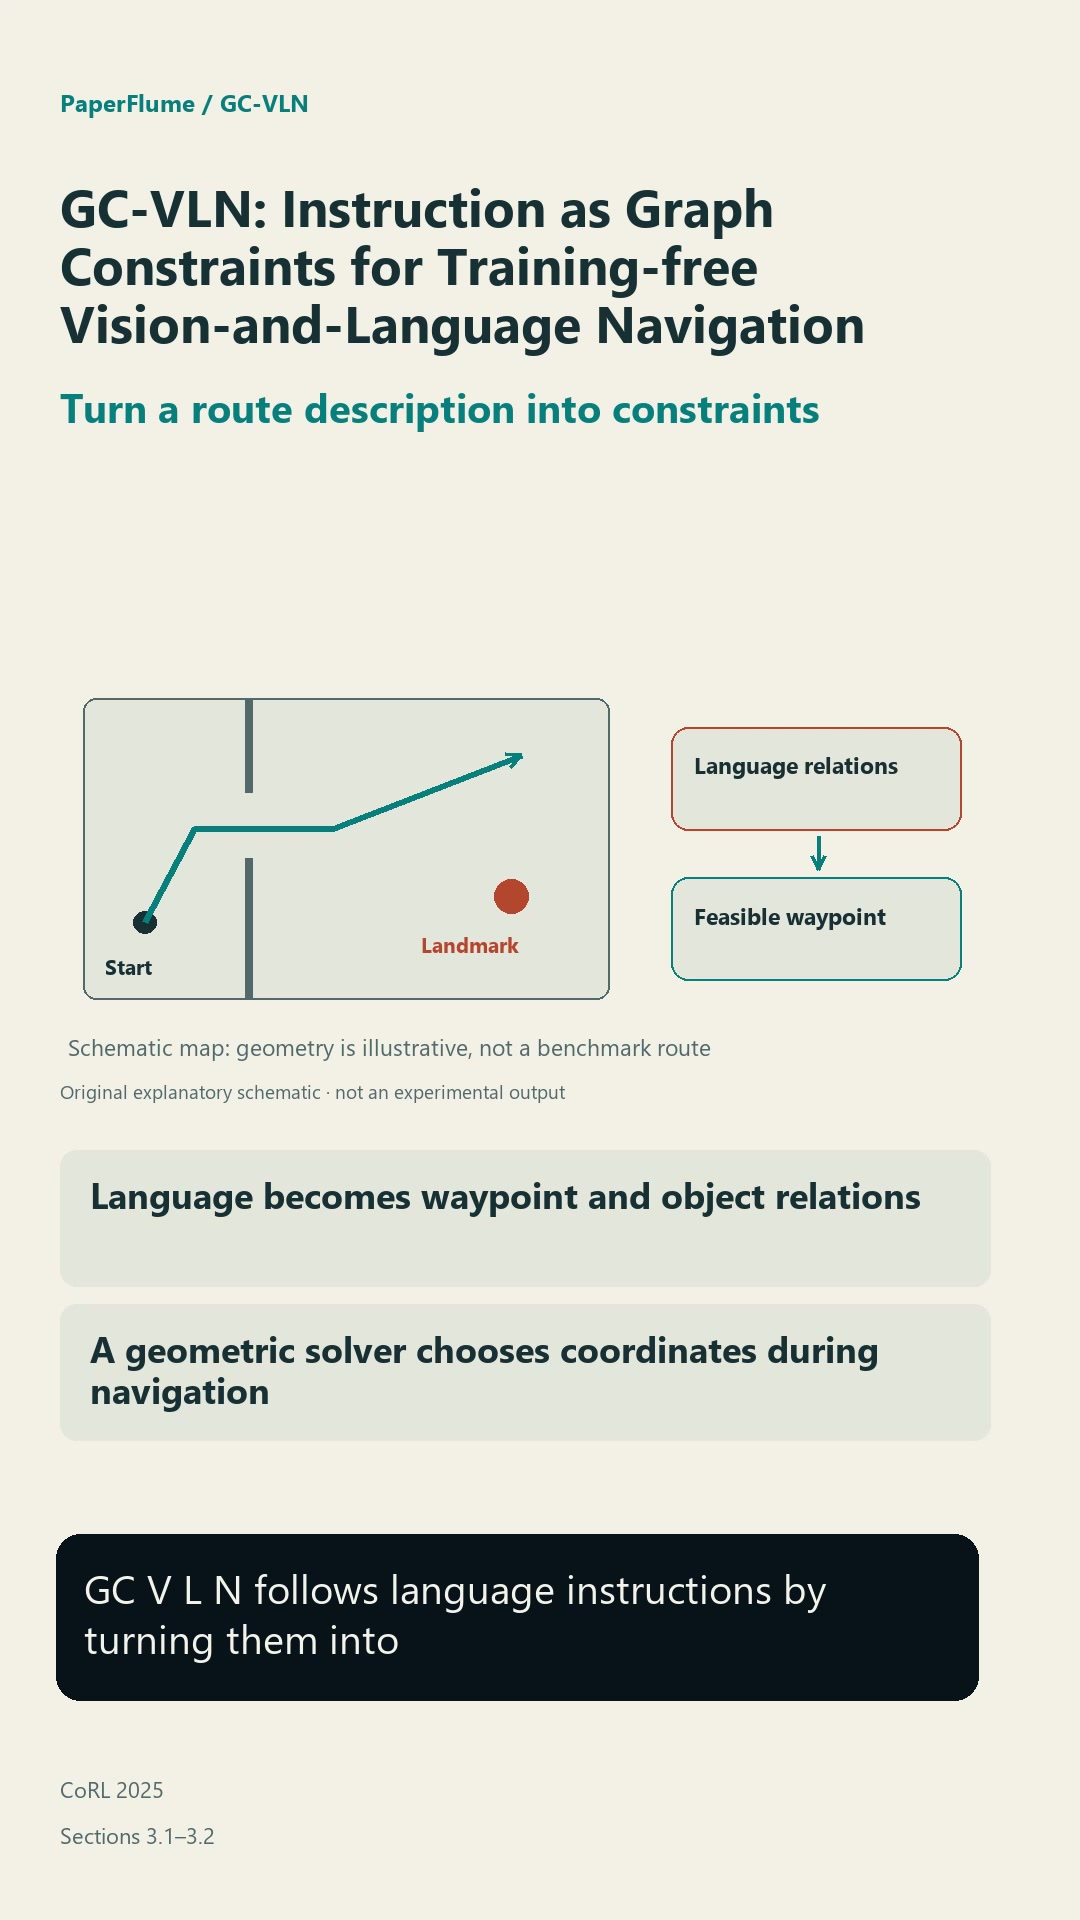 0:58
GC-VLN: Instruction as Graph Constraints for Training-free Vision-and-Language Navigation
shares Vision-language navigation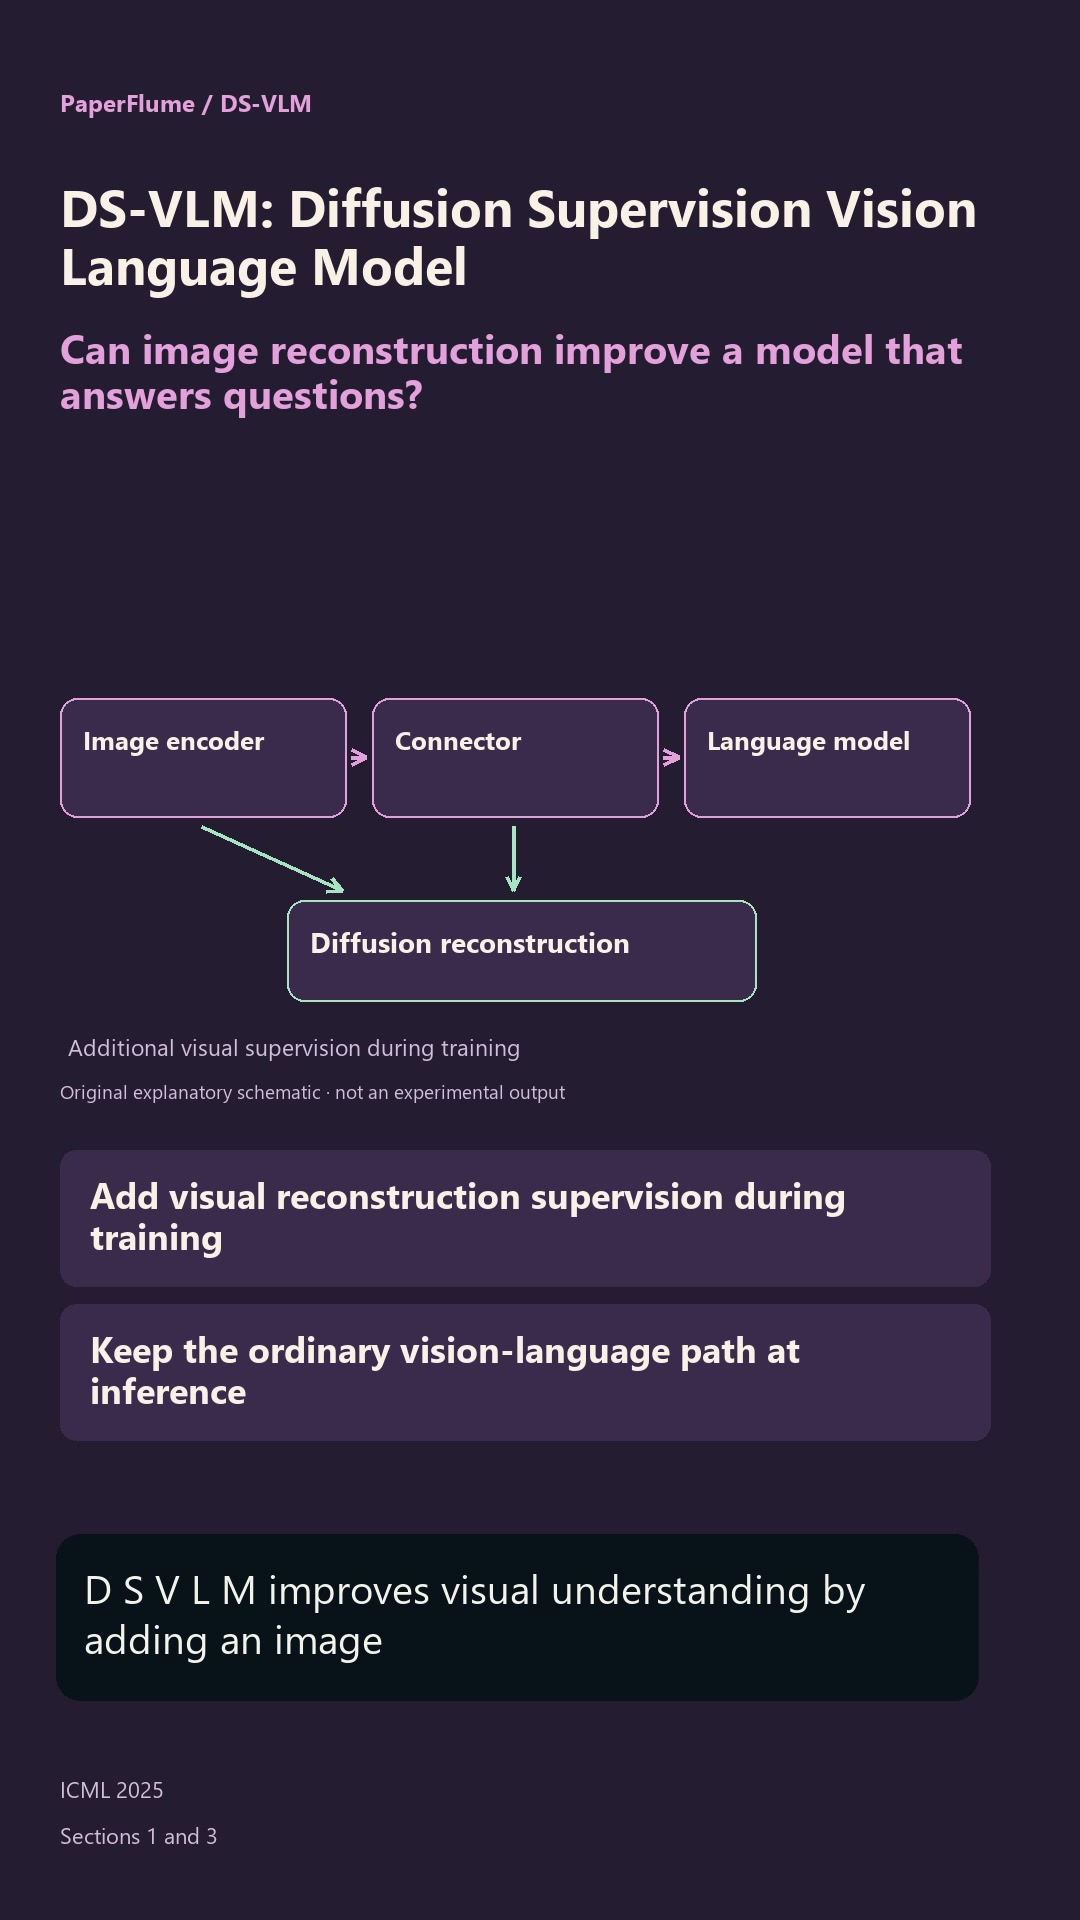 1:00