Next
Papers near this one.
Walkthroughs
 7:19
MoDA: Modulation Adapter for Fine-Grained Visual Understanding in Instructional MLLMs
shares Multimodal fusion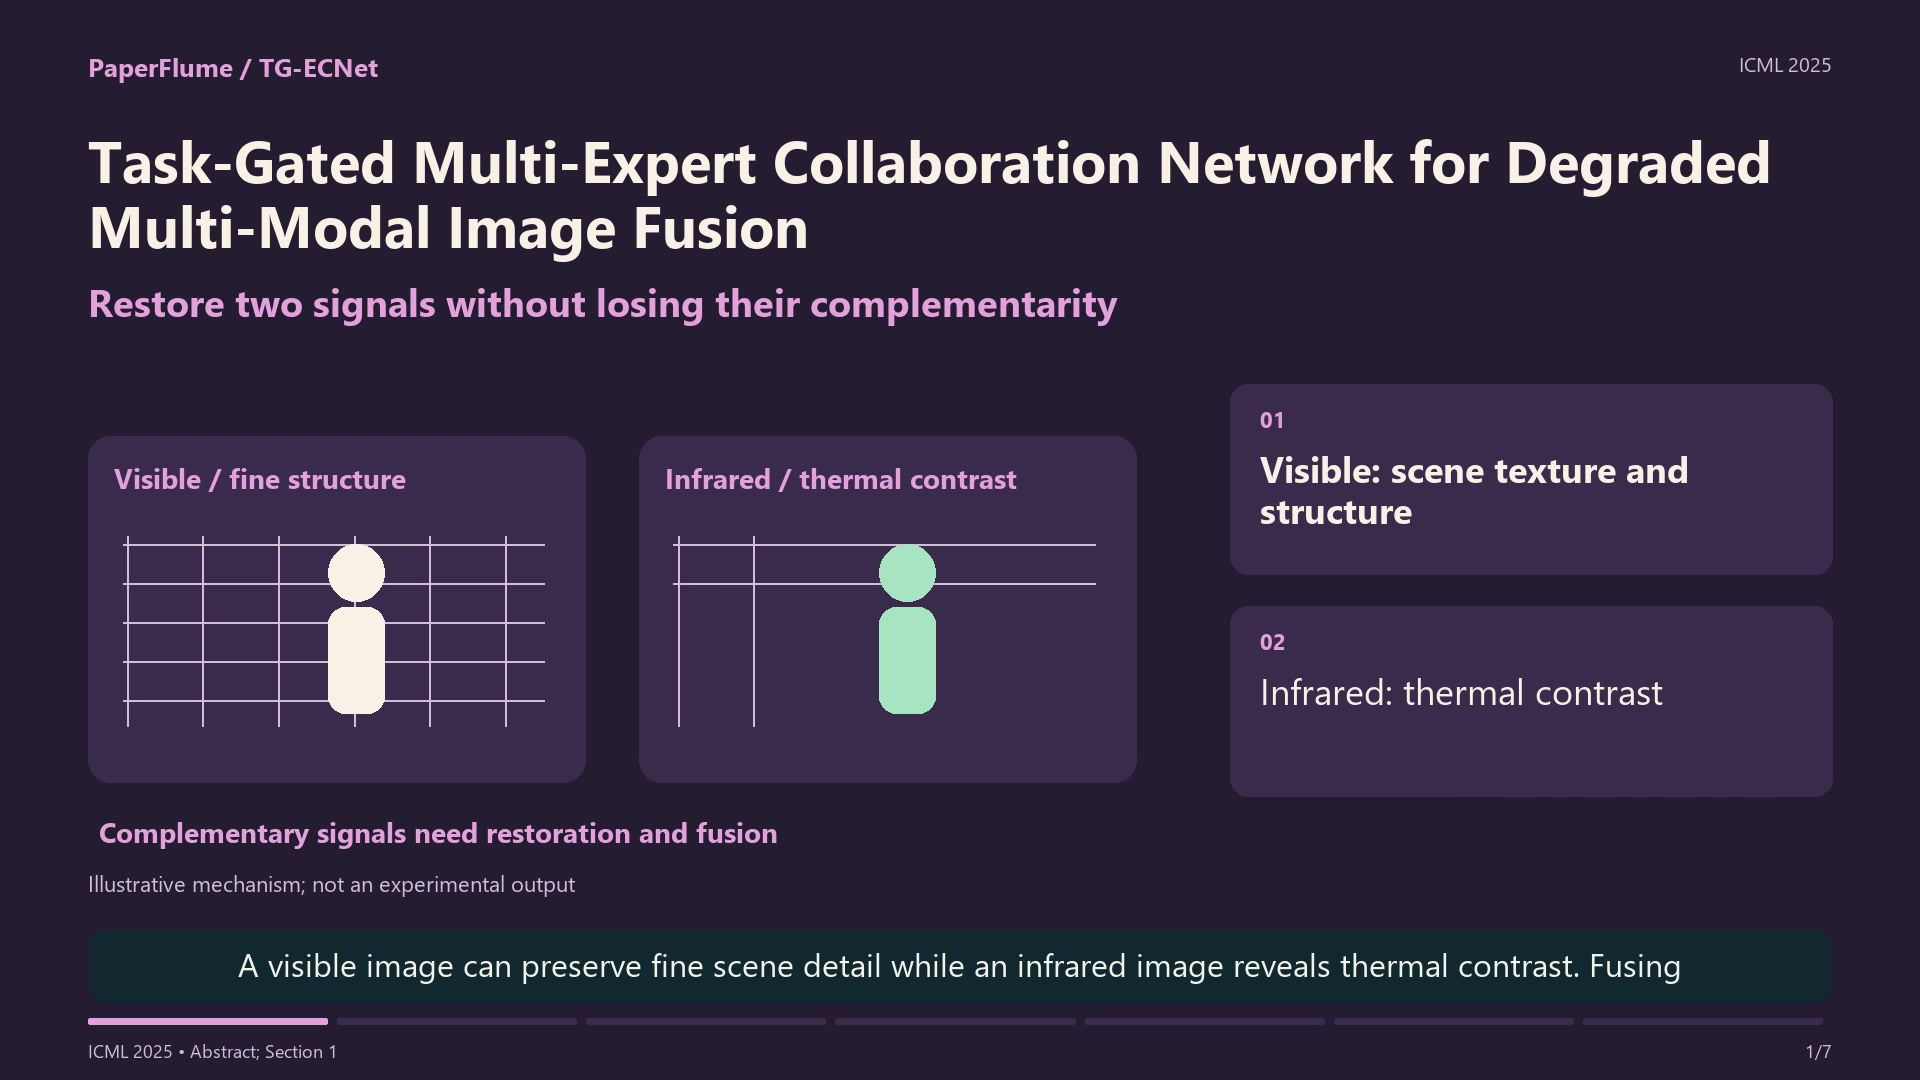 5:39
Task-Gated Multi-Expert Collaboration Network for Degraded Multi-Modal Image Fusion
shares Multimodal fusion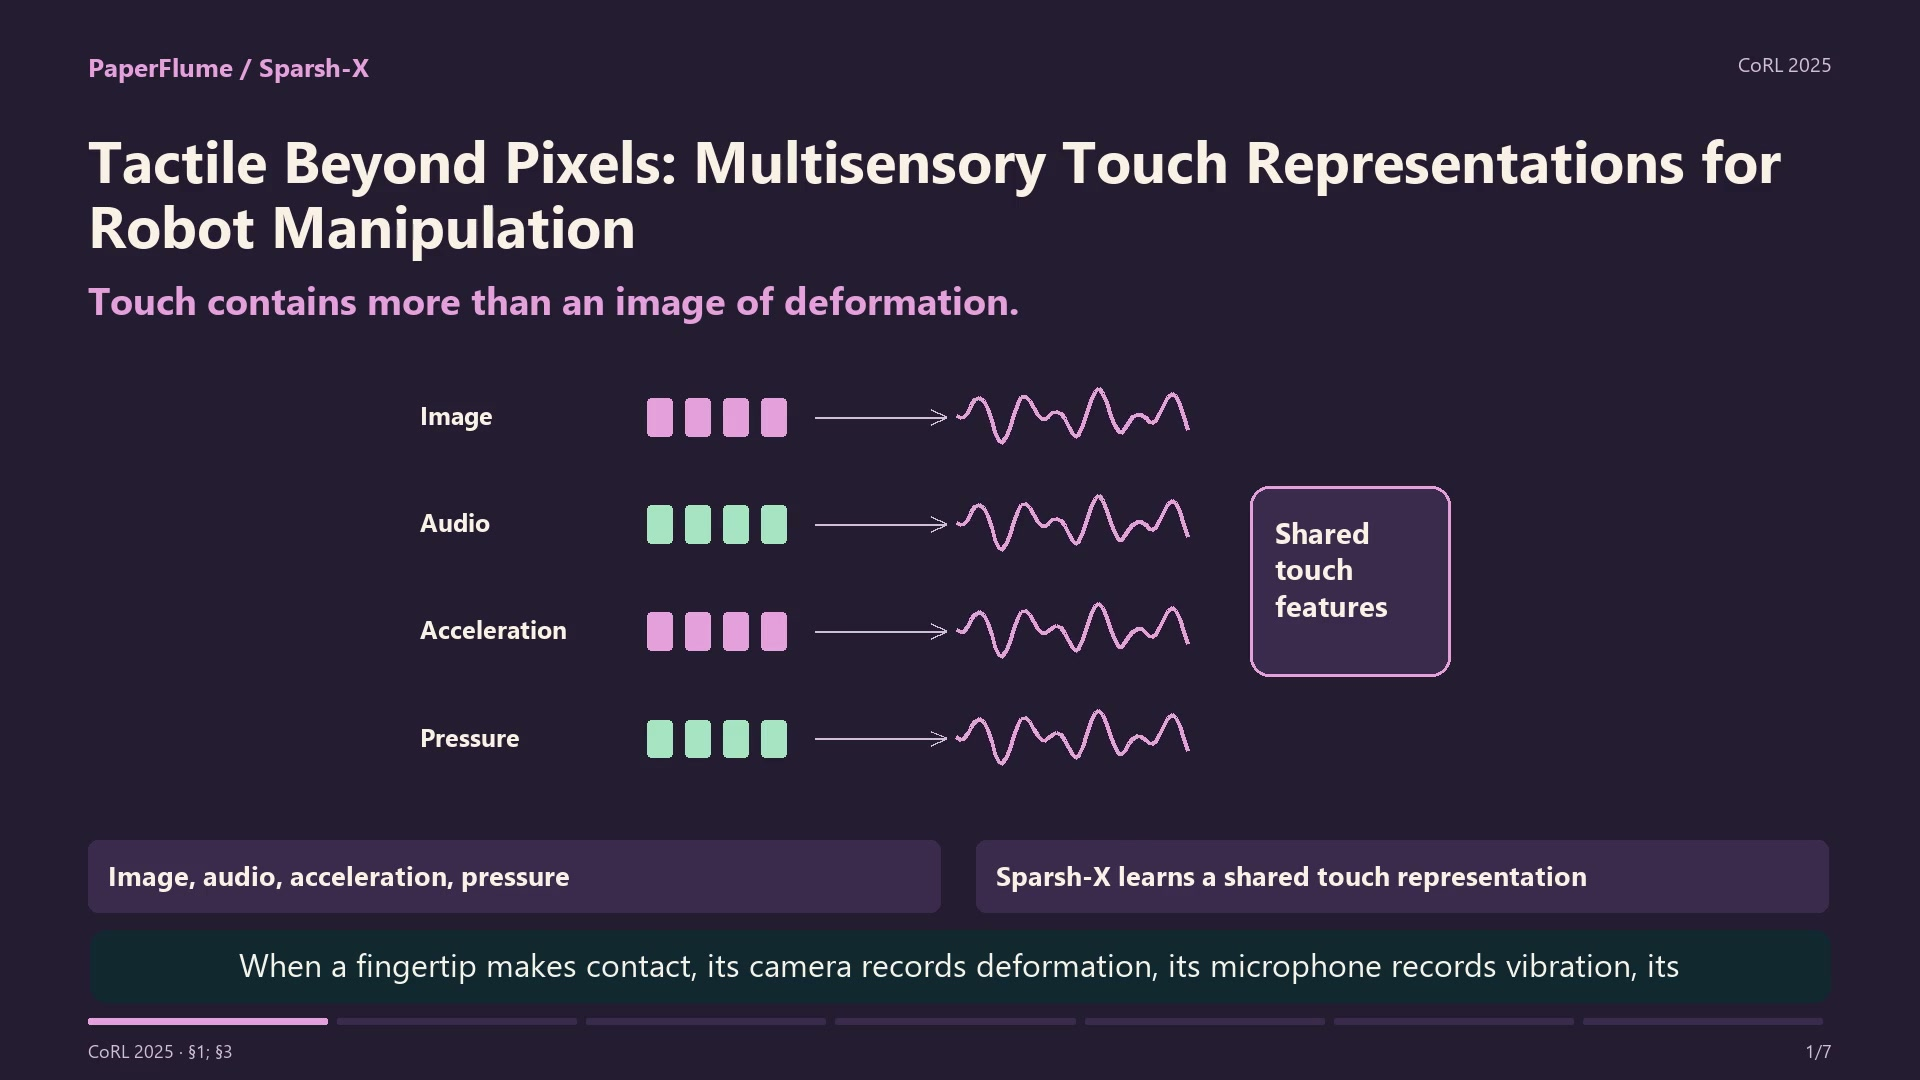 4:20
Tactile Beyond Pixels: Multisensory Touch Representations for Robot Manipulation
shares Multimodal fusionShort cuts
 0:54
MoDA: Modulation Adapter for Fine-Grained Visual Understanding in Instructional MLLMs
shares Multimodal fusion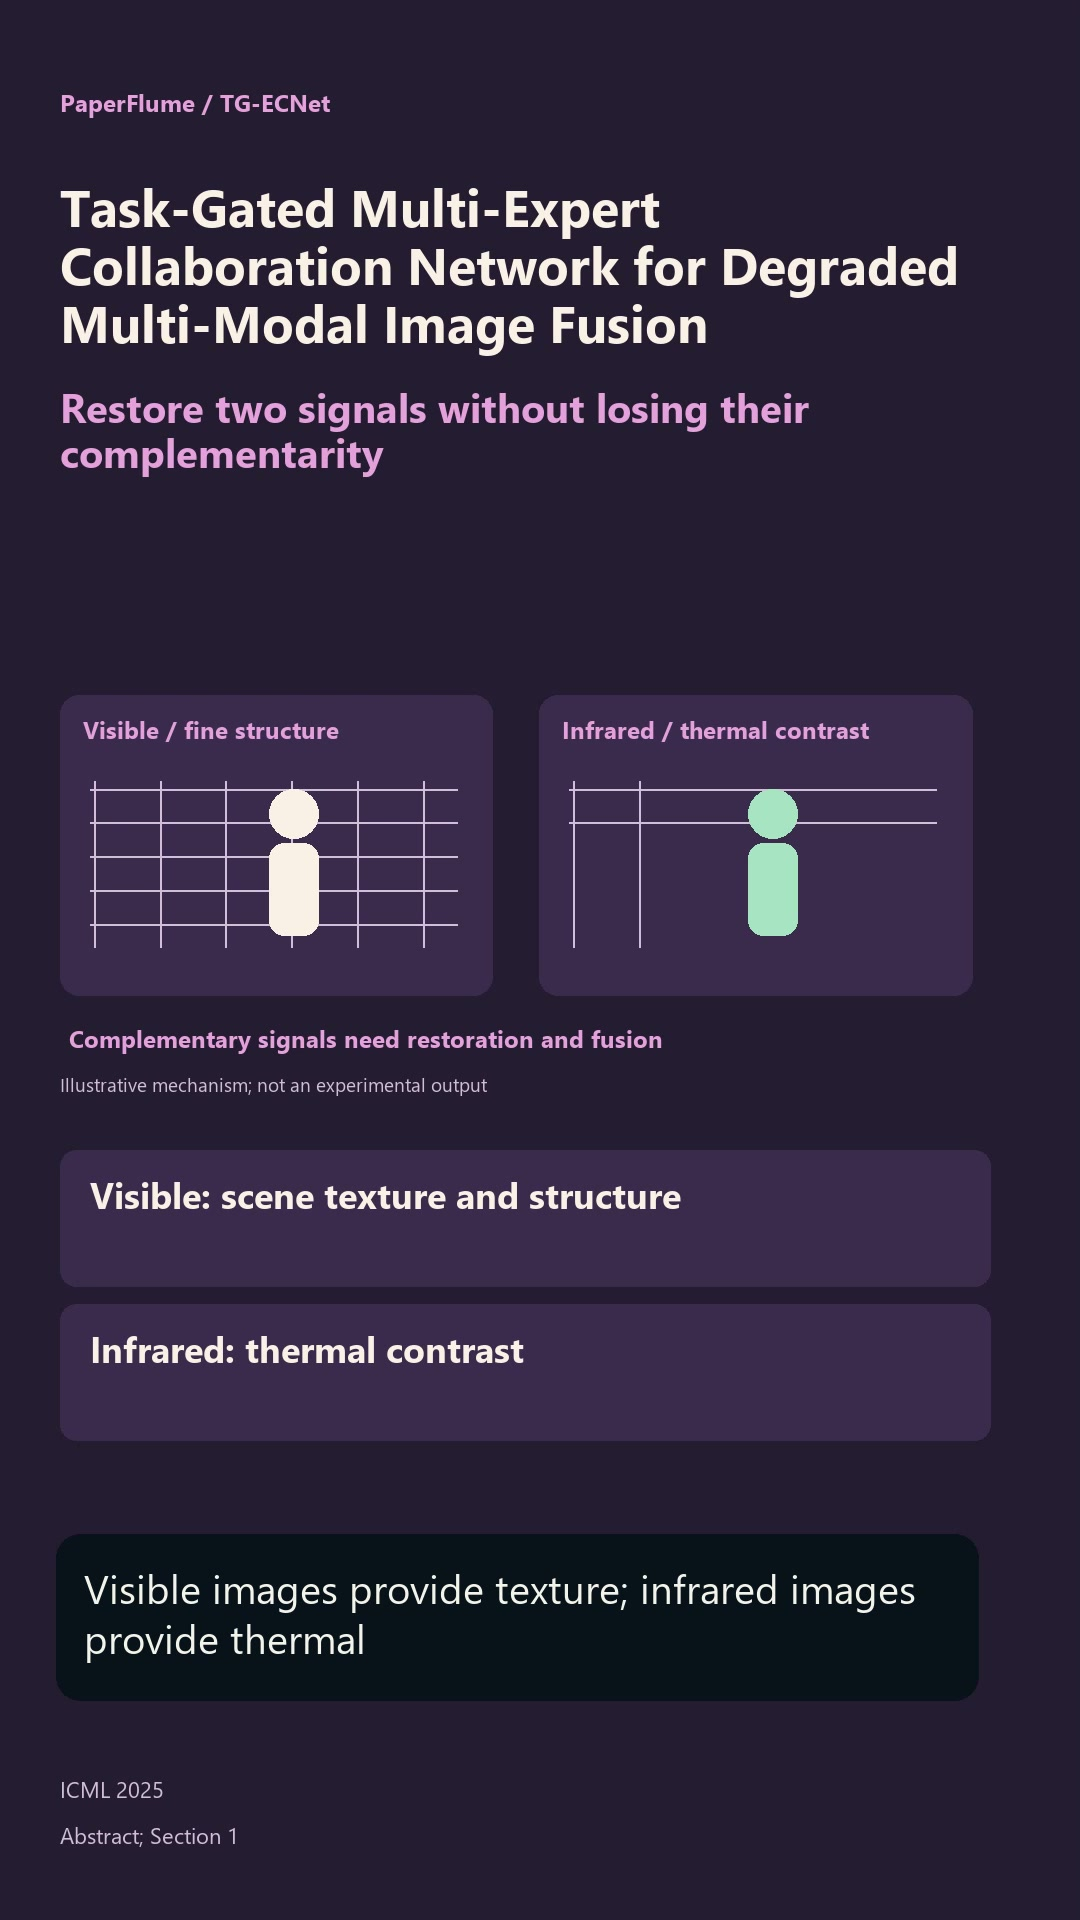 0:58
Task-Gated Multi-Expert Collaboration Network for Degraded Multi-Modal Image Fusion
shares Multimodal fusion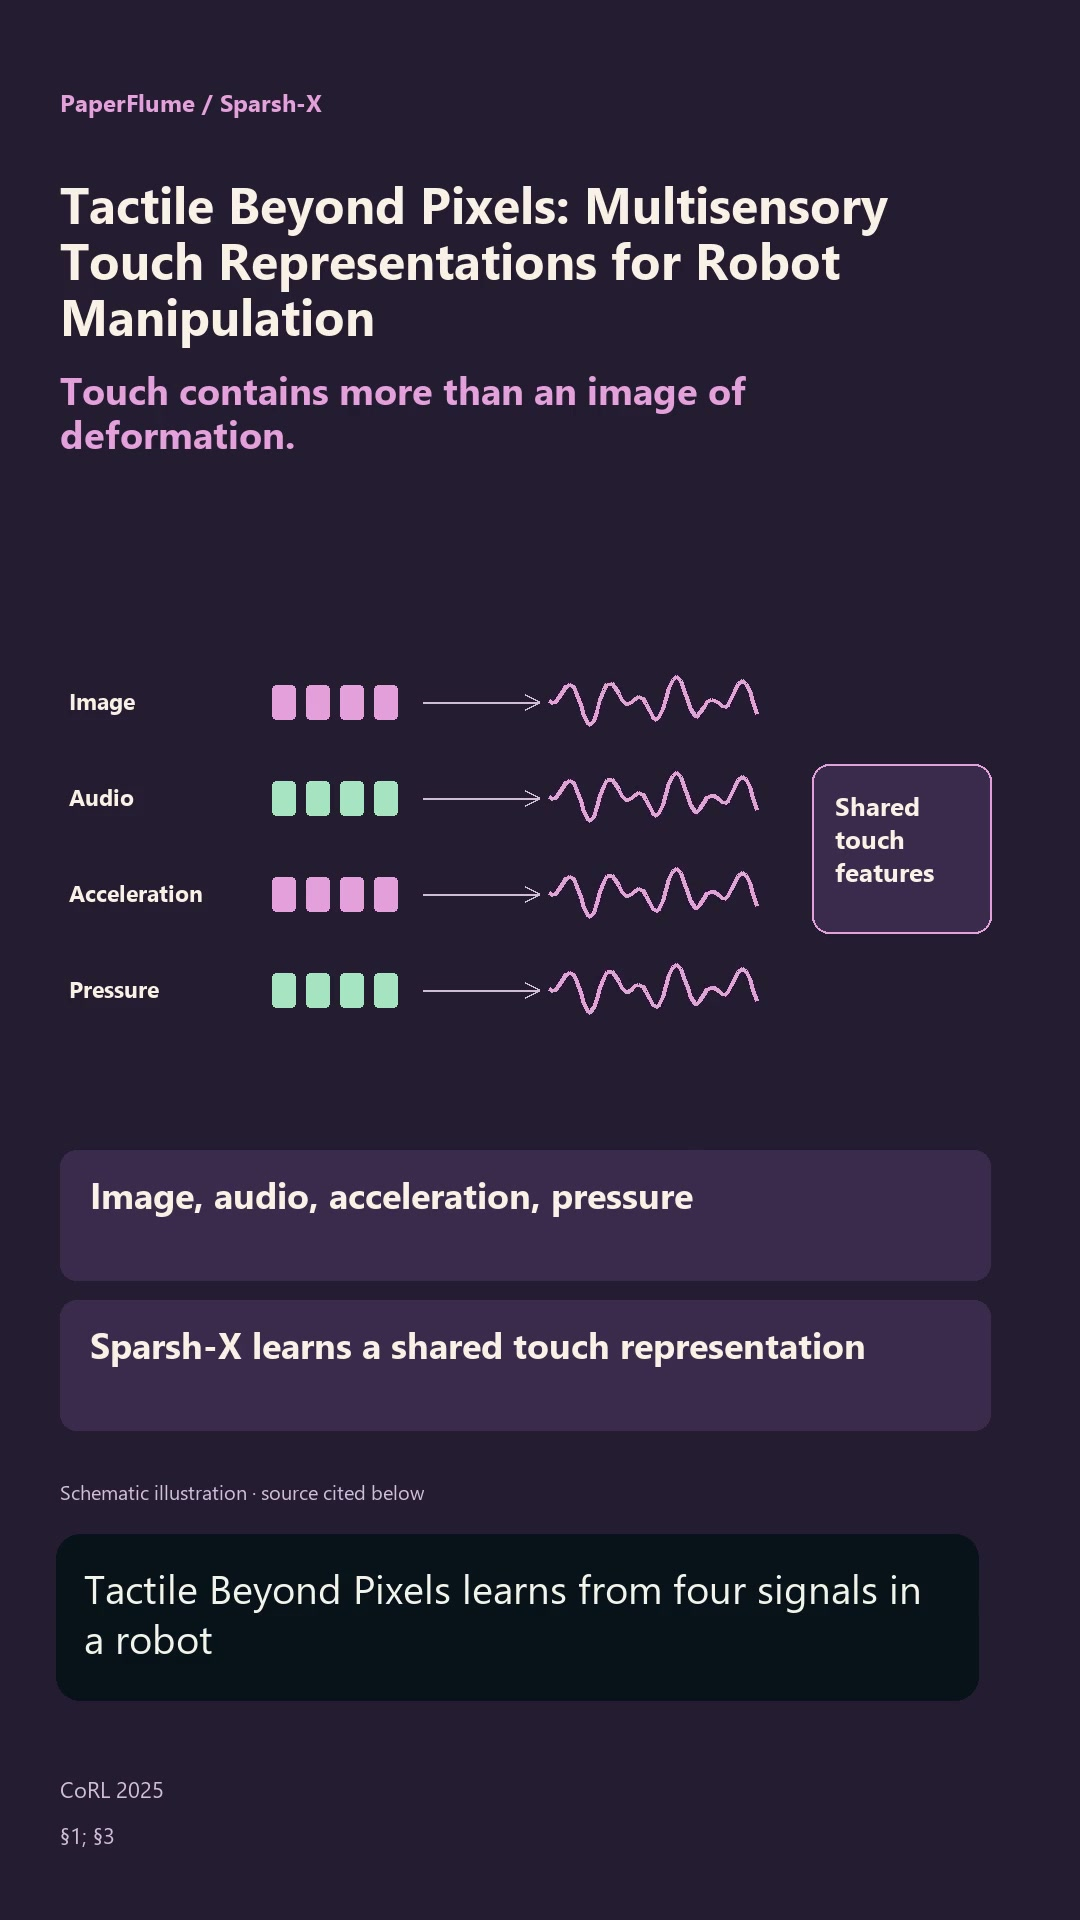 0:53