Next
Papers near this one.
Walkthroughs
 5:28
Active Exploring like a Pigeon: Reinforcing Spatial Reasoning via Agentic Vision-Language Models
shares Video understanding 6:44
SciVideoBench: Benchmarking Scientific Video Reasoning in Large Multimodal Models
shares Video understanding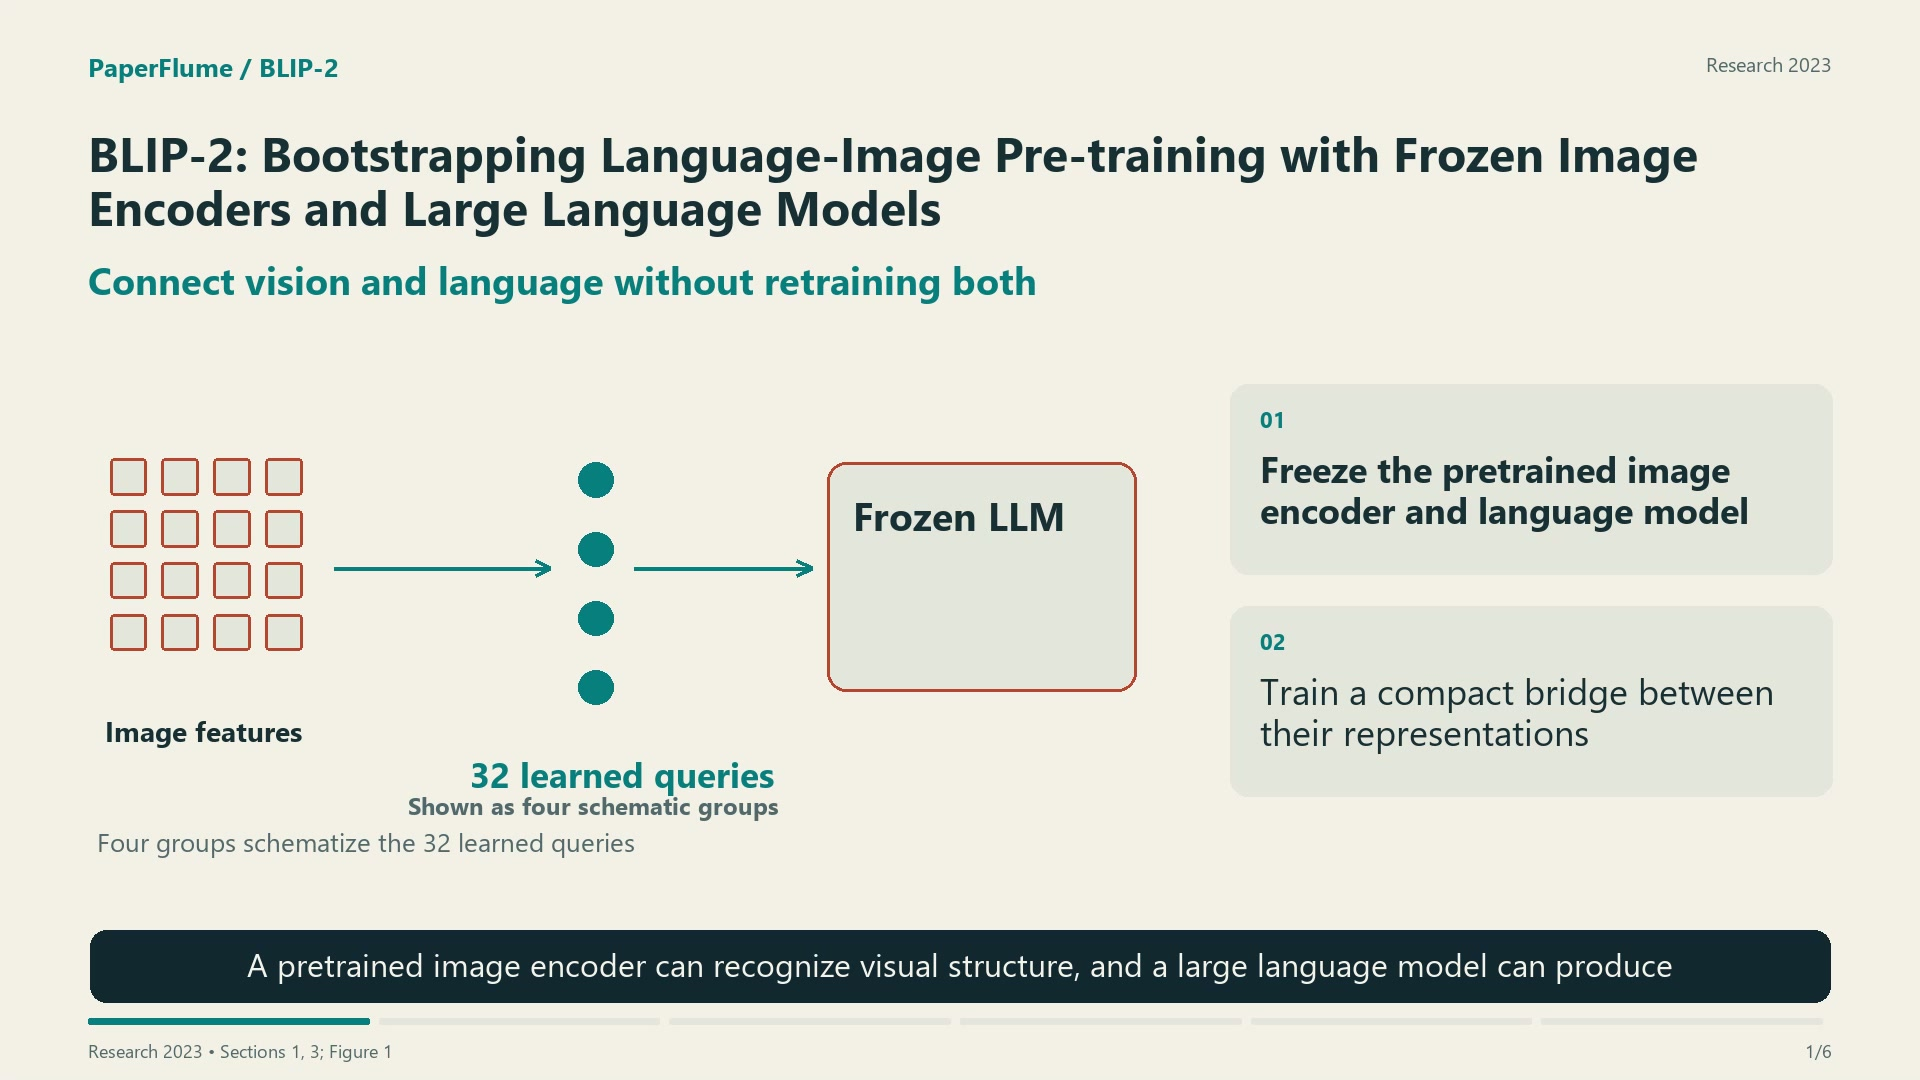 4:08
BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models
shares Multimodal LLMsShort cuts
 0:59
Active Exploring like a Pigeon: Reinforcing Spatial Reasoning via Agentic Vision-Language Models
shares Video understanding 0:54
SciVideoBench: Benchmarking Scientific Video Reasoning in Large Multimodal Models
shares Video understanding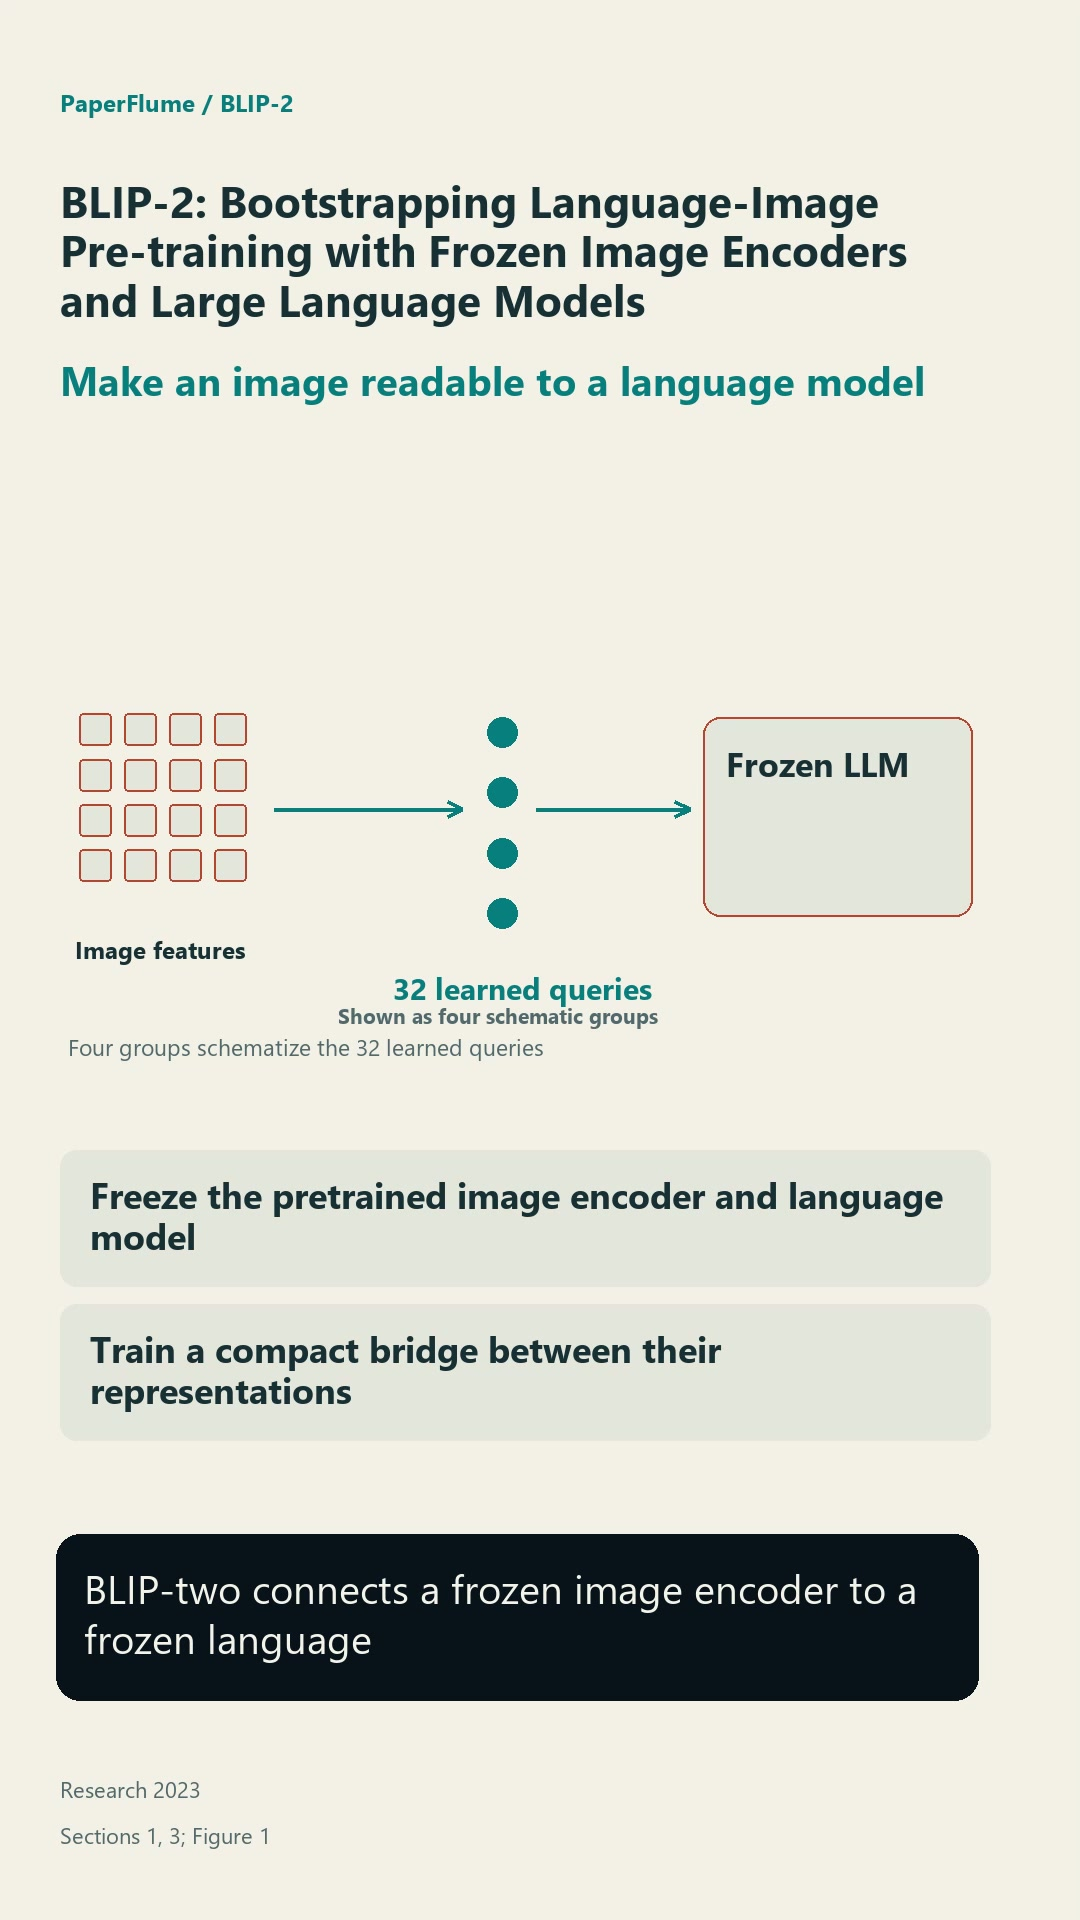 0:40