Next
Papers near this one.
Walkthroughs
 4:12
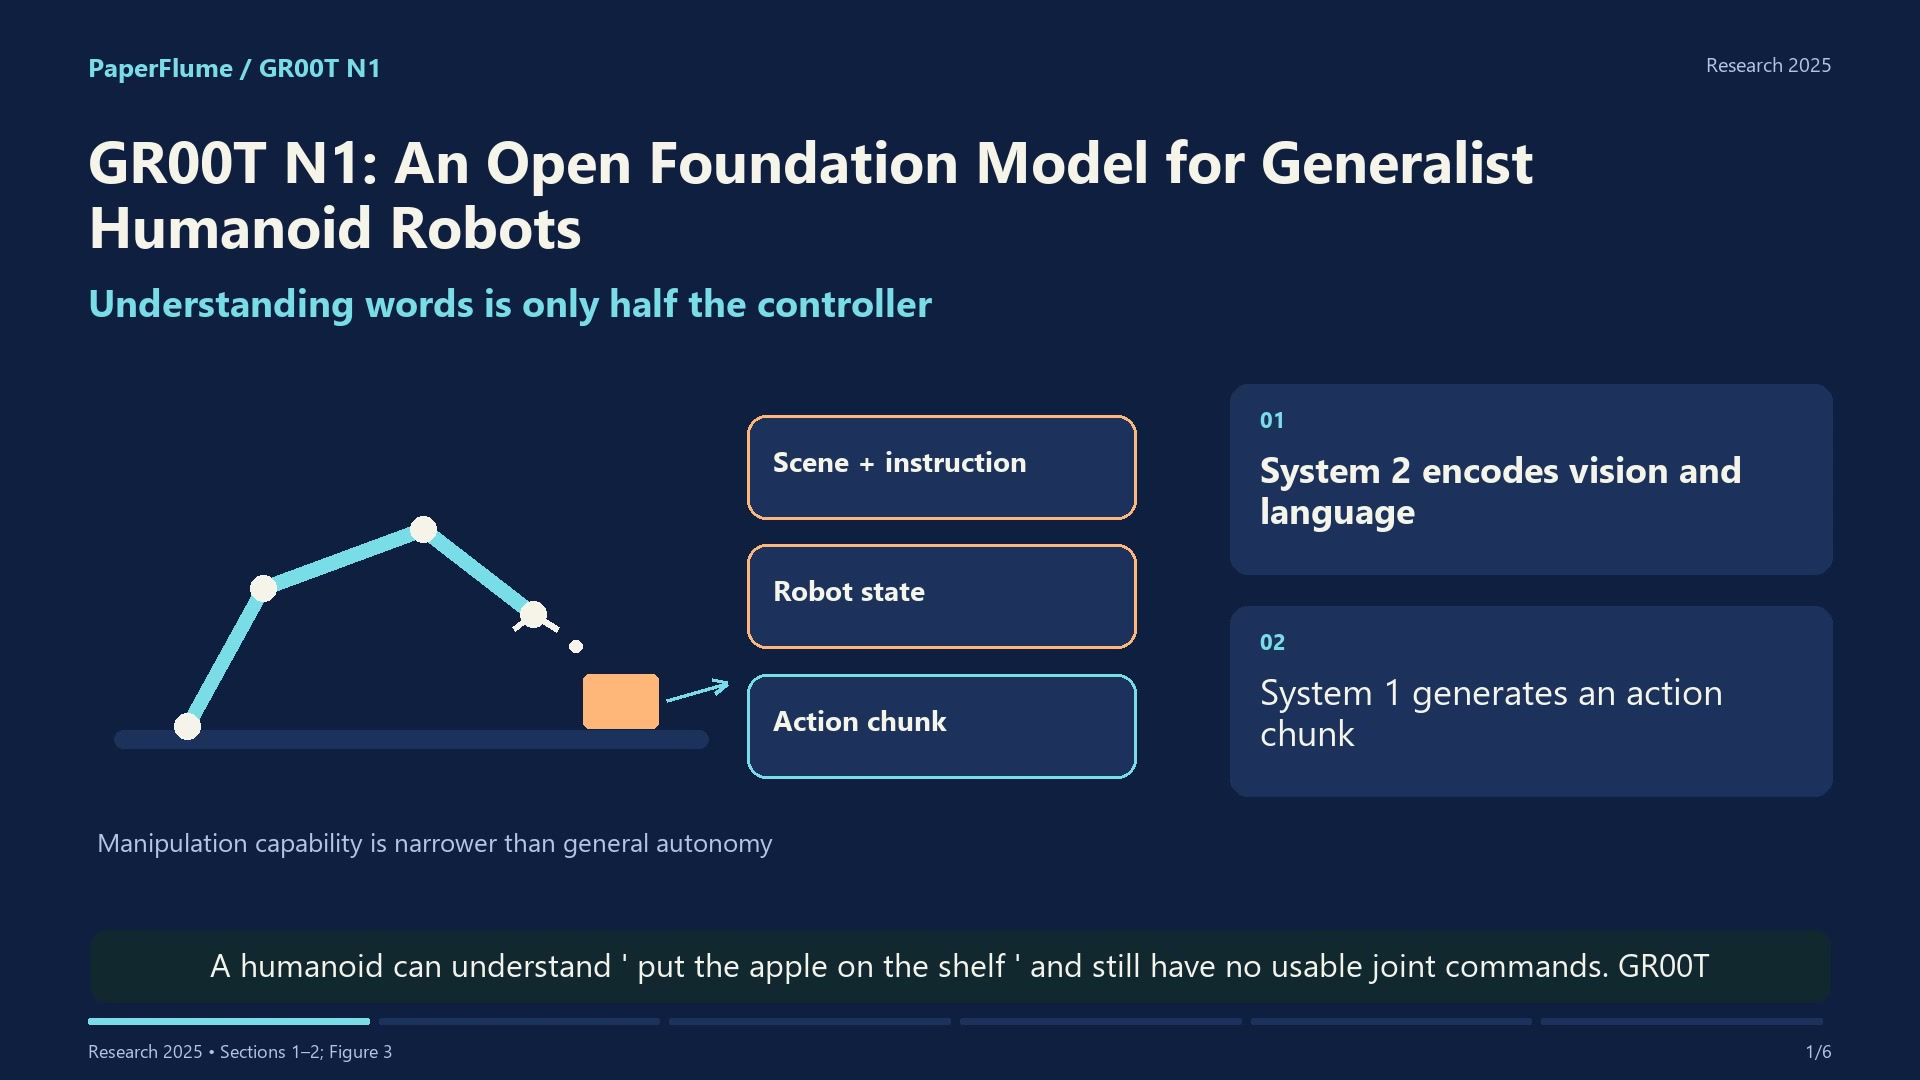
GR00T N1: An Open Foundation Model for Generalist Humanoid Robots
2503.14734
shares VLA models
 6:45
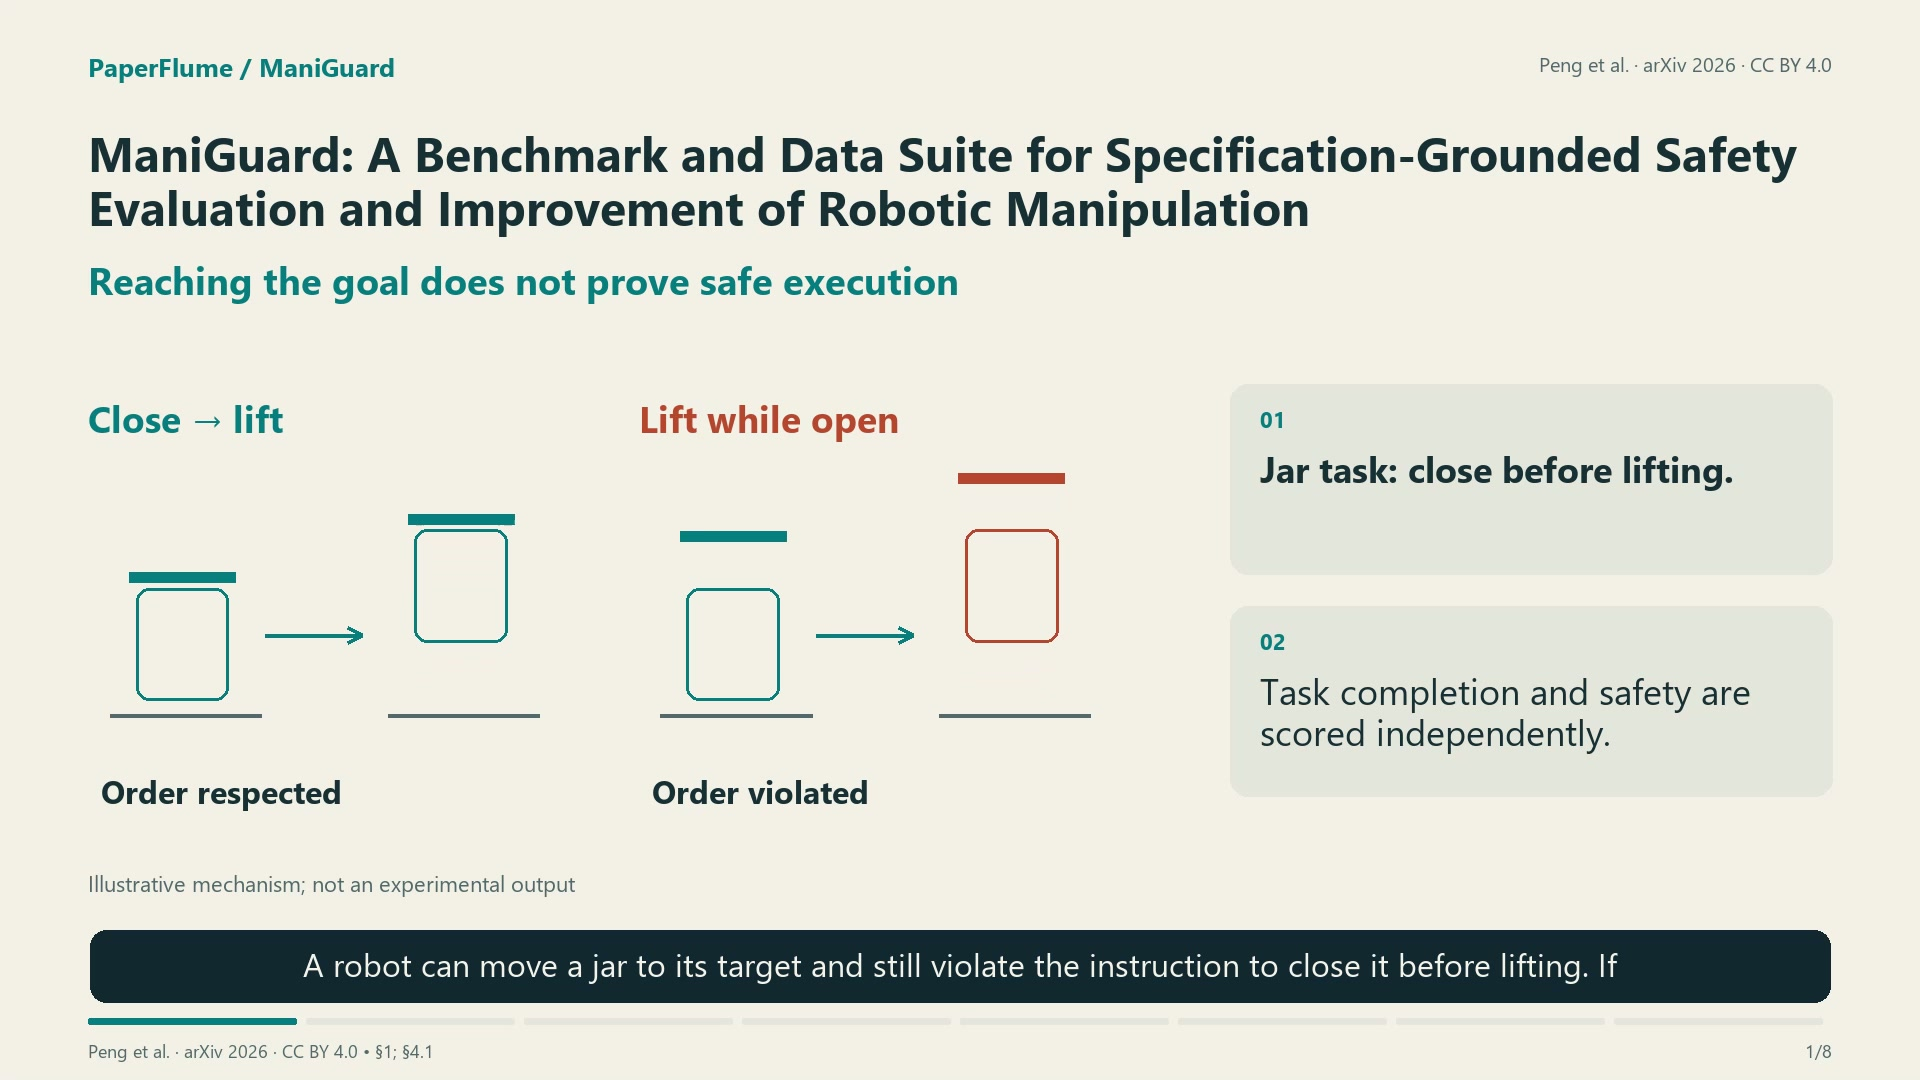
ManiGuard: A Benchmark and Data Suite for Specification-Grounded Safety Evaluation and Improvement of Robotic Manipulation
2608.17386
shares VLA models
 7:16
Tabero: Learning Gentle Manipulation with Closed-Loop Force Feedback from Vision, Touch, and Language
shares GraspingShort cuts
 0:42
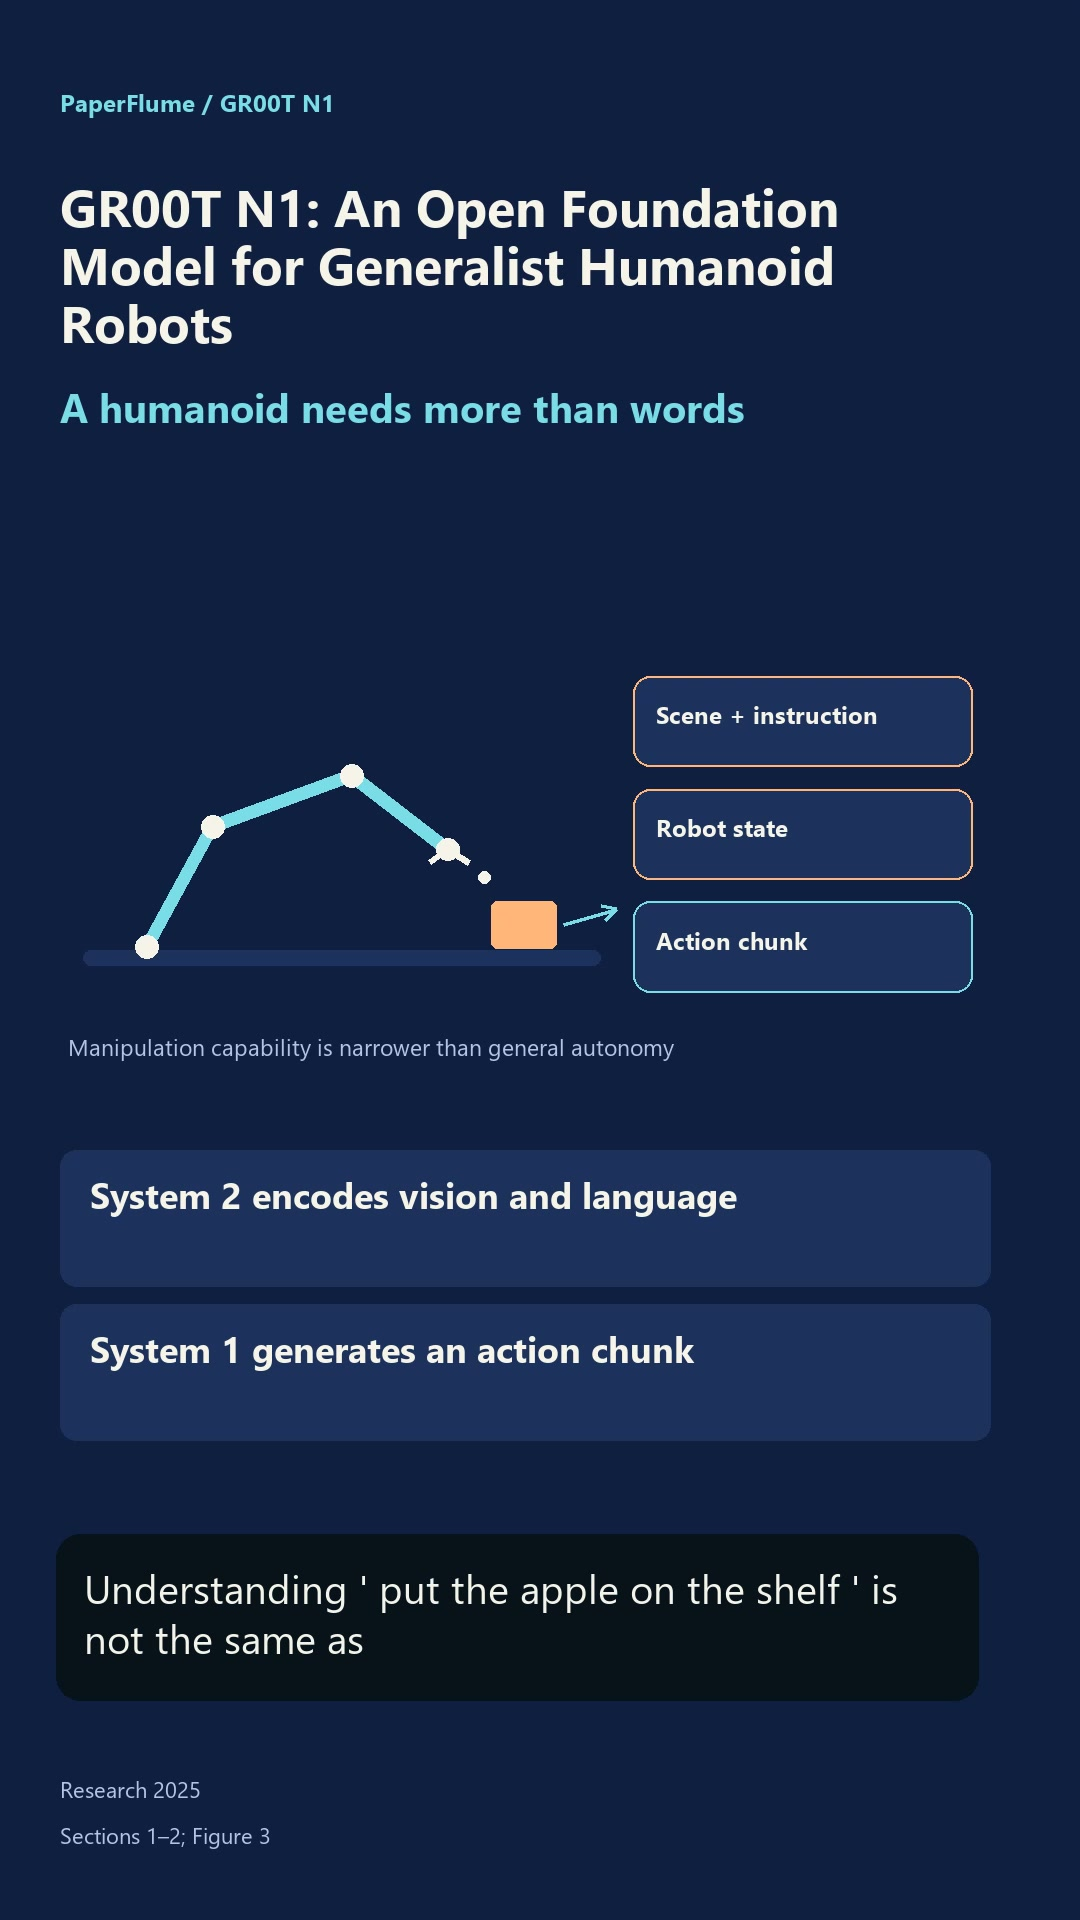
GR00T N1: An Open Foundation Model for Generalist Humanoid Robots
2503.14734
shares VLA models
 0:57
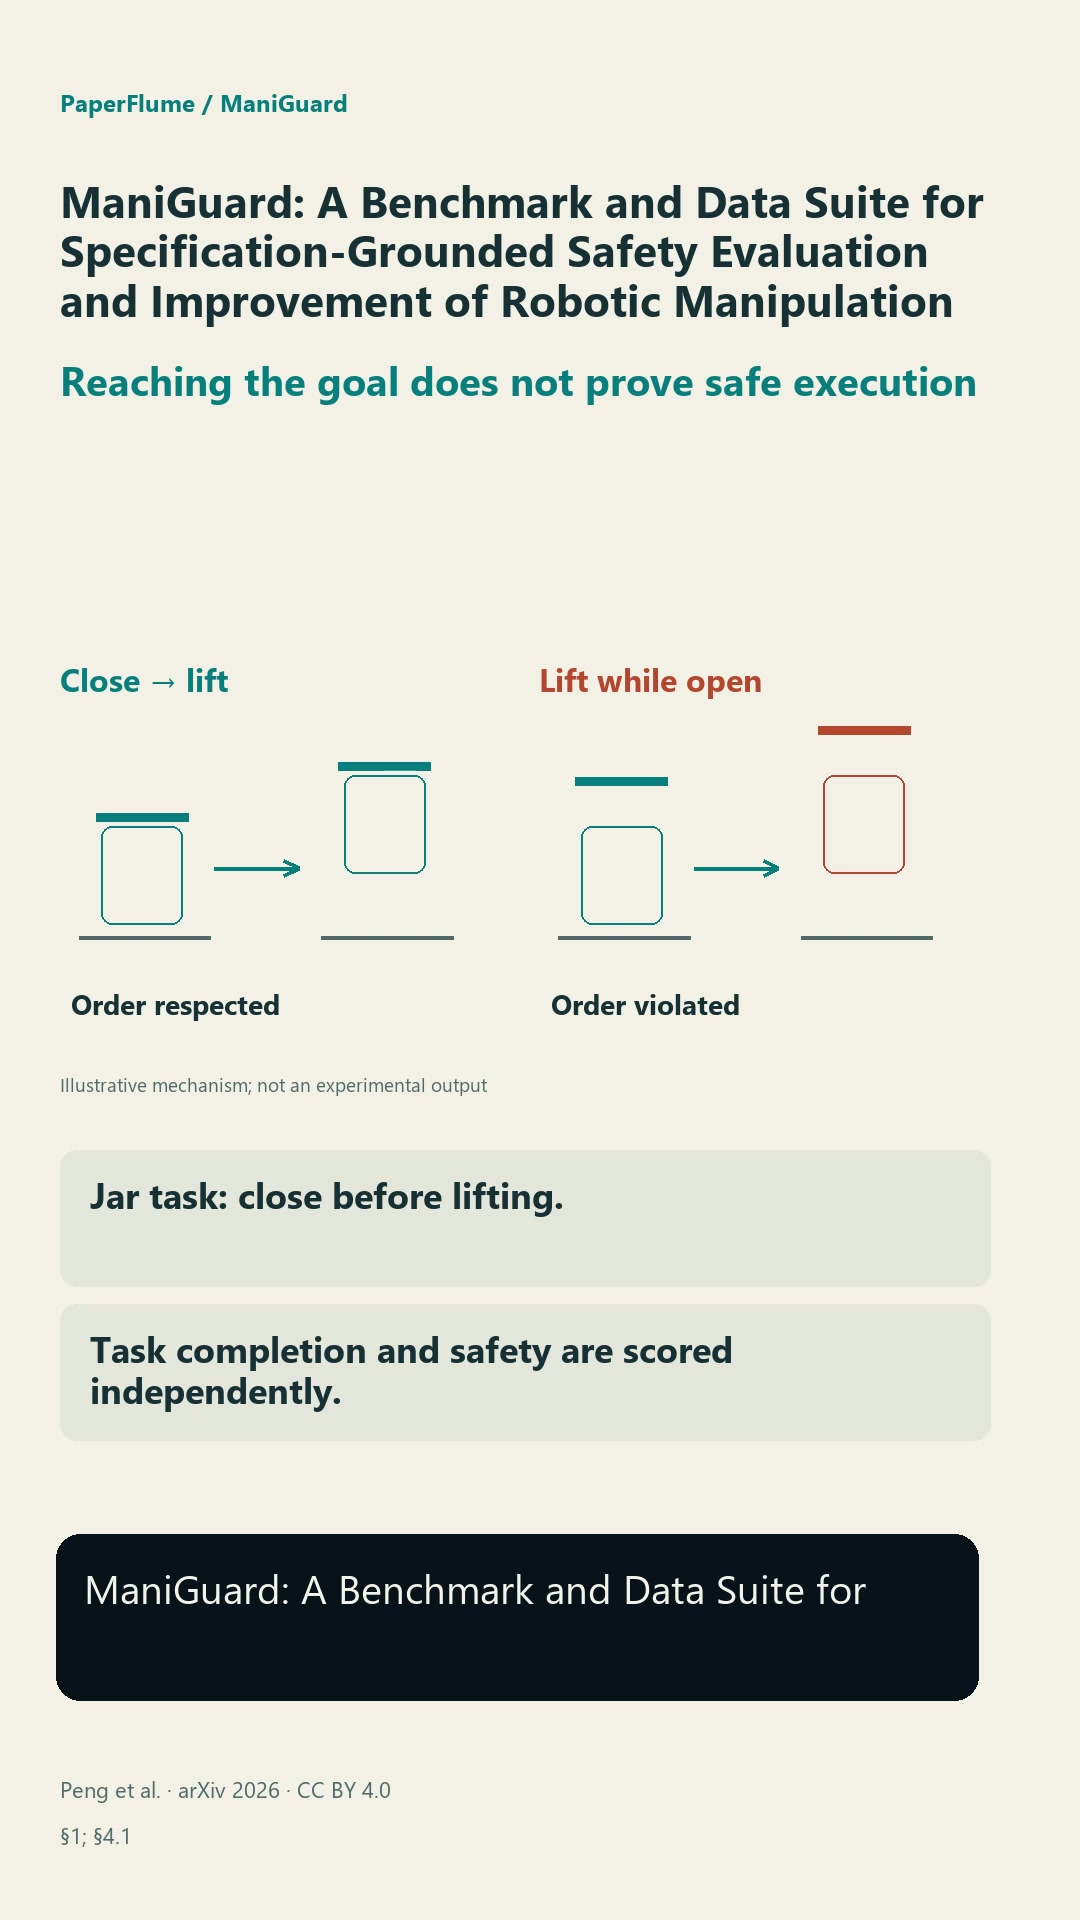
ManiGuard: A Benchmark and Data Suite for Specification-Grounded Safety Evaluation and Improvement of Robotic Manipulation
2608.17386
shares VLA models
 0:56